AI Engineering: from jargon to business impact.
We build AI that pays for itself.
What it costs to run
Not cost per token. Cost per resolved ticket, per generated report, per whatever your business already counts. Then the same figure at ten times the traffic, before you find out the hard way.
How often someone has to check it
The share of outputs that go straight through. This is the number that decides whether the feature saved anyone time, and it is the one most teams cannot answer.
How it impacts your revenue
The reason the feature exists. More conversions, faster resolution, fewer people needed per unit of work. We agree which line is supposed to move before we start, and measure it where your finance team already looks.
Engagement
01
Audit
5 to 10 days
We read the code, the traces and the bills, then tell you which of the three is actually holding the feature back: what it costs to run, how often someone has to check it, or what it is doing to revenue.
02
Build
8 to 12 weeks
Let us agree on the outcome and the scope. Then define milestones and deliver incrementally.
03
Embedded
monthly
Embedded into your team. Architecture, implementation, code review and support, all done together.
04
Team workshop
Various durations, on-site or remote
Time with your engineers on retrieval, evaluation and what production actually demands. Hands on keyboards, in your codebase where possible.
Recent
Eval-Driven Development, LLM-Generated SQL, and the Cost-Uncertainty-Lag Triangle
LangChain Interrupt, San Francisco, 2026
How an agent platform moved from a hierarchy of agents to a single flat one, traded a large tool catalogue for a handful of general tools, and let the model write SQL against the schema directly. Presented with Akash Ashok on Rippling's agent platform.
Who you work with
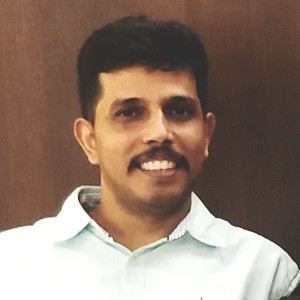
Senthil Velu Sundaram
Twenty years of building and running software. A decade at ThoughtWorks, then fintech at Simpl, and currently consulting on AI/ML for a US HR technology platform. He spoke at LangChain Interrupt in San Francisco this year on evaluation and agent architecture.
Questions
How do engagements start?
A call, then a short written scope. Most teams start with the Audit because it is the cheapest way to find out whether the problem you think you have is the one you actually have. Nothing obliges you to continue after it.
Who owns the code?
You do, on delivery, including the evaluation suites and tooling. We keep no licence over anything built for you.
Do you work with our engineers or around them?
With them. We write code in your repository, in your review process, and the handover is continuous rather than an event at the end. If your team cannot run the system without us, we have not finished.
What happens to our data?
We work inside your infrastructure and your accounts wherever possible. Where evaluation needs real traffic, we agree the handling and retention in writing first. We do not move your data into our own systems.
Remote or on-site?
Both. We are based in Dubai and work across US and European hours regularly. Workshops are on-site. Build work is mostly remote with visits at the points where being in the room matters.
What if we already have something in production?
That is the usual case, and it is the easier one. There is real traffic to build evaluations from and a real cost curve to read, rather than guesses about both.
Start with the audit.
A fixed fee and a written answer to which number is actually holding you back. Nothing obliges you to continue after it.